
Microsoft Unveils Maia 300 Chip, Targets Million-Unit Rollout
Microsoft's third-generation Maia chip uses 2nm and 3nm chiplets and claims 40% more compute per megawatt than leading GPU systems.
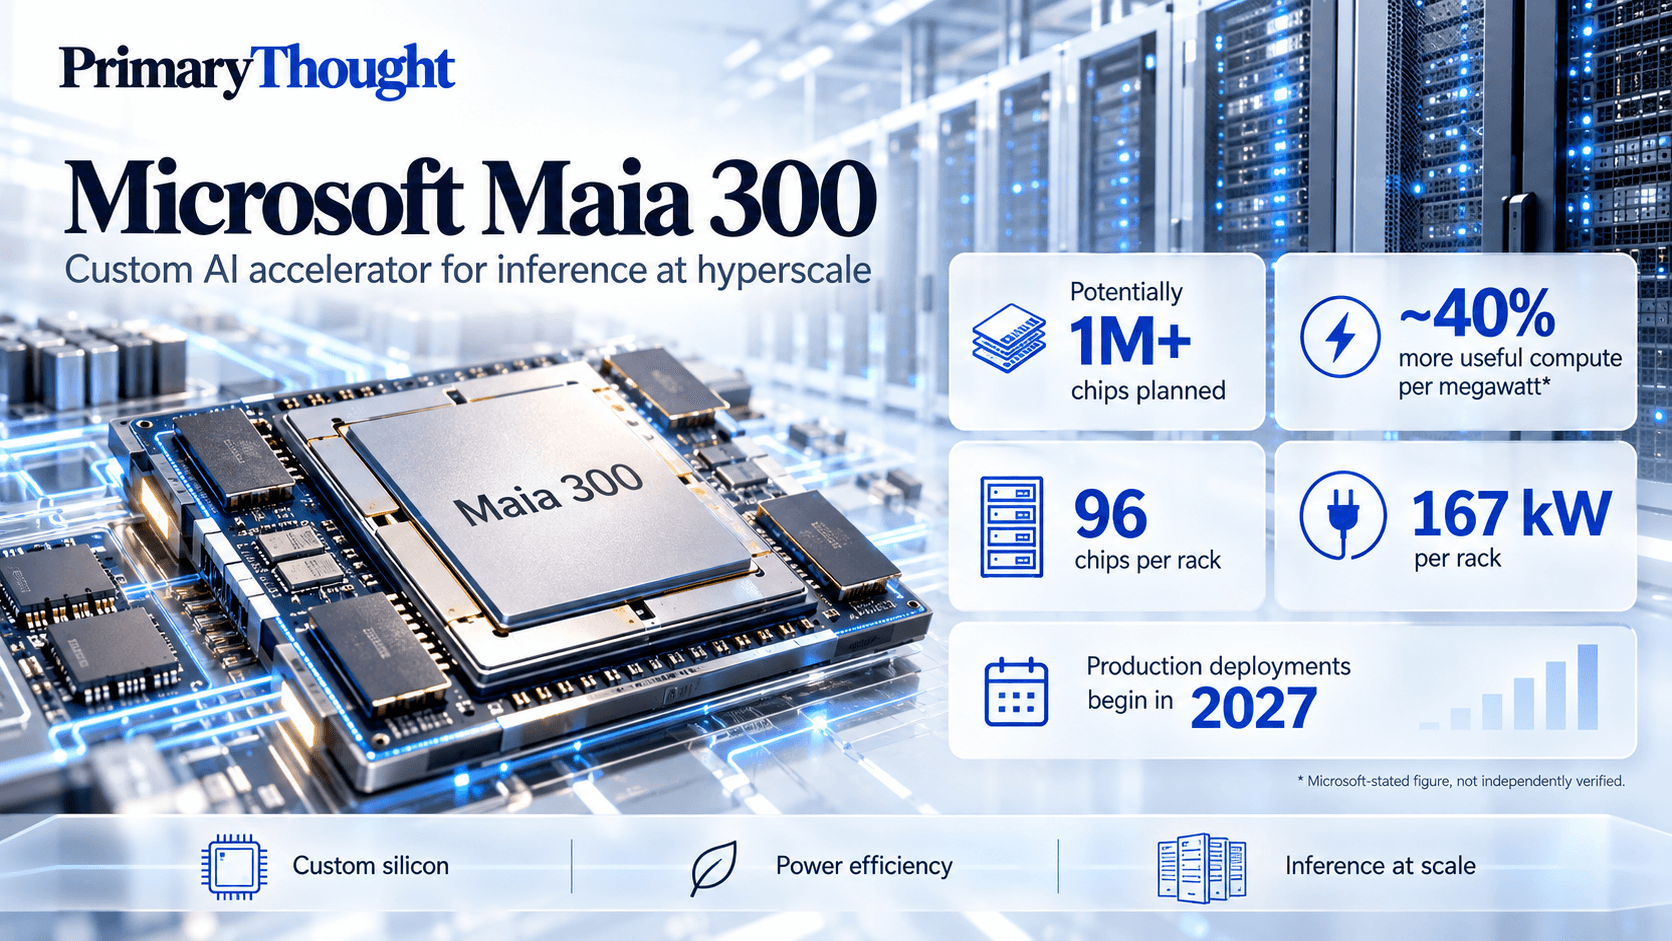
Microsoft has unveiled Maia 300, the third generation of its in-house AI accelerator, and says it plans to deploy potentially more than a million of the chips next year. The announcement, made on 12 October 2026, matters because it is one of the clearest signs yet that the largest cloud operators intend to run a growing share of their own AI workloads on custom silicon rather than on Nvidia GPUs alone.
The company is pitching the chip primarily on efficiency. According to Microsoft, Maia 300 delivers roughly 40% more useful computing per megawatt than leading GPU-based systems. That is a company claim, and as of this writing, it has not been independently tested.
What Microsoft announced
As reported by Reuters in a story republished by The Spokesman-Review, Maia 300 is built for AI workloads such as coding and complex business tasks. Microsoft plans what it calls "multi-gigawatt deployments" starting next year, with potentially more than a million units in service to support its own AI services. The predecessor chip already runs Microsoft's in-house models and OpenAI models on Azure, according to the same report.
A write-up by FourWeekMBA, citing Microsoft, adds that Scott Guthrie, who leads Microsoft's cloud and AI business, wrote that Maia 300 will begin production deployments in 2027 and that the goal is to make the Maia family the primary inference system for Microsoft products and services. The roundup presents the 40% figure as an expectation rather than a measured result.
Rani Borkar, president of Azure hardware systems and infrastructure at Microsoft, summarised the pitch to Reuters as delivering "more intelligence for every watt, every dollar, and every byte of memory."
How the chip is built
Reuters reports that Maia 300 takes a chiplet approach. The central processor uses TSMC's 2-nanometre technology for key computing functions, while other chiplets use cheaper 3-nanometre technology for tasks such as moving data inside the system. Reuters notes that this differs from Nvidia's design, which pairs one large compute chip with surrounding high-bandwidth memory.
The rack-level numbers are where the efficiency argument becomes concrete. According to the Reuters report, a Maia 300 rack holds 96 chips and draws about 167 kilowatts, while Nvidia's GB300 rack holds 72 GPUs and draws 142 kilowatts. Those figures are not directly comparable on their own, since the racks hold different numbers of chips and the report does not give a like-for-like throughput measurement. Microsoft did not name the GPU-based systems it used for the 40% comparison.
For context, Techzine reported in August that the previous generation, Maia 200, is manufactured on TSMC's 3nm process, has more than 140 billion transistors, delivers over 10 petaFLOPS at 4-bit precision within a 750-watt power budget, and carries 216GB of HBM3e memory with 272MB of on-chip SRAM. Techzine also said that chip was designed for inference rather than training. Maia 300 appears to follow the same inference-first logic, although Microsoft's statements reported so far describe it in terms of AI workloads and inference systems generally, not detailed specifications.
Why it matters
The scale of the stated plan is the headline. Microsoft expects capital expenditure of more than $175 billion this calendar year, according to Reuters, and a meaningful fraction of the compute that spending buys will determine how much of it flows to Nvidia and how much to Microsoft's own designs and its chip manufacturing partner, TSMC.
Custom silicon offers hyperscalers three things. The first is cost: a chip designed around a company's own models and serving stack can be cheaper per token than a general-purpose GPU. The second is power: data-centre capacity is increasingly limited by electricity, so performance per megawatt is becoming as important as performance per dollar. The third is negotiating leverage with suppliers. Reuters frames the announcement as part of a wave of custom chips from cloud rivals and AI firms such as OpenAI aimed at reducing Nvidia's dominance in AI computing.
It is worth separating what is confirmed from what is projected. Confirmed, in the sense that Microsoft stated it publicly: the existence of Maia 300, the process technology, the rack configuration, and the intention to deploy at very large scale. Projected: the efficiency advantage, the deployment volumes, and the timing. Production deployments are described as beginning in 2027, so the efficiency claims are about systems that customers cannot yet buy or measure.
Timeline and open questions
The timeline has shifted in coverage over recent months. In August, Techzine quoted Andrew Wall, general manager of Azure Maia, as saying Maia 300 was expected sometime in 2027, which is consistent with the production schedule now described. The same Techzine report, relaying earlier reporting by The Information, said Microsoft was negotiating with TSMC for capacity to produce more than 300,000 units with delivery scheduled for 2027, and that Microsoft wanted to persuade major customers such as Anthropic to use the chip. The Information's reporting rested on unnamed sources, and Microsoft's announced ambition of potentially more than a million units is considerably larger than that earlier figure. The two are not necessarily in conflict, since one concerns a negotiation reported in August and the other a company plan stated in October, but the gap illustrates how much of the volume story remains unsettled.
Several questions will determine whether Maia 300 changes the market:
External availability. Whether Microsoft offers Maia capacity to Azure customers directly, or keeps it for first-party services and partner models, will shape its commercial impact.
Independent benchmarks. The 40% figure compares against unnamed GPU systems. Third-party measurements on real inference workloads will say more than any vendor slide.
Supply. A 2-nanometre compute die depends on leading-edge TSMC capacity, which many companies are competing for. Whether volumes reach the stated scale depends on manufacturing, packaging and memory supply.
Software. Nvidia's advantage rests heavily on its software ecosystem. Moving models onto a custom accelerator takes engineering effort, which is easier for a company running a limited set of its own and partner models than for a broad customer base.
The wider hardware picture
Maia 300 was one of several data-centre hardware announcements on the same day. According to the FourWeekMBA roundup, AMD described an open blueprint for agentic AI infrastructure called Helion, with one example configuration, a CPU-only rack, supporting up to 32,768 CPU cores and availability planned for November 2026. Nvidia said it contributed Vera Rubin rack and compute tray designs to the Open Compute Project through its MGX architecture, with Meta adopting its Spectrum-6 Ethernet switches. Marvell announced second-generation Structera X CXL memory expanders, with the 3406 model expected to sample in the first quarter of 2027. The roundup labels the performance figures in these items as company claims.
Taken together, the announcements show competition moving beyond the accelerator itself to racks, networking, memory and power delivery. Microsoft's rack-level framing, 96 chips and 167 kilowatts per rack, reflects that shift: buyers increasingly evaluate whole systems and what each megawatt of data-centre capacity yields.
What to watch next
The next few months should clarify whether the stated plans hold. Watch for formal specifications, since the public details so far cover process technology and rack configuration but not peak throughput or memory capacity. Watch for any named external customers. And watch for how Nvidia and other suppliers respond on efficiency, given that performance per megawatt is now the metric Microsoft chose to lead with. Until production deployments begin in 2027, Maia 300 is best read as a statement of strategic direction backed by substantial spending, with its real-world efficiency still to be demonstrated.
Frequently Asked Questions
What is Maia 300?
Maia 300 is the third generation of Microsoft's custom AI chip, announced on 12 October 2026 for AI workloads such as coding and complex business tasks.
What efficiency does Microsoft claim?
Microsoft says it delivers about 40% more useful computing per megawatt than leading GPU-based systems, without naming the systems compared. The claim is unverified.
When will Maia 300 be deployed?
Microsoft plans multi-gigawatt deployments starting next year, with production deployments described as beginning in 2027.
How is Maia 300 built?
Per Reuters, it uses chiplets, with TSMC 2nm technology for key compute and cheaper 3nm chiplets for data movement.