
Ai2 Releases Olmo-core 3, an Open MoE Training Stack
Ai2's Olmo-core 3 is an open training stack for mixture-of-experts models, with self-reported 52,000 tokens/sec/GPU on a 47B MoE and candid failure notes.
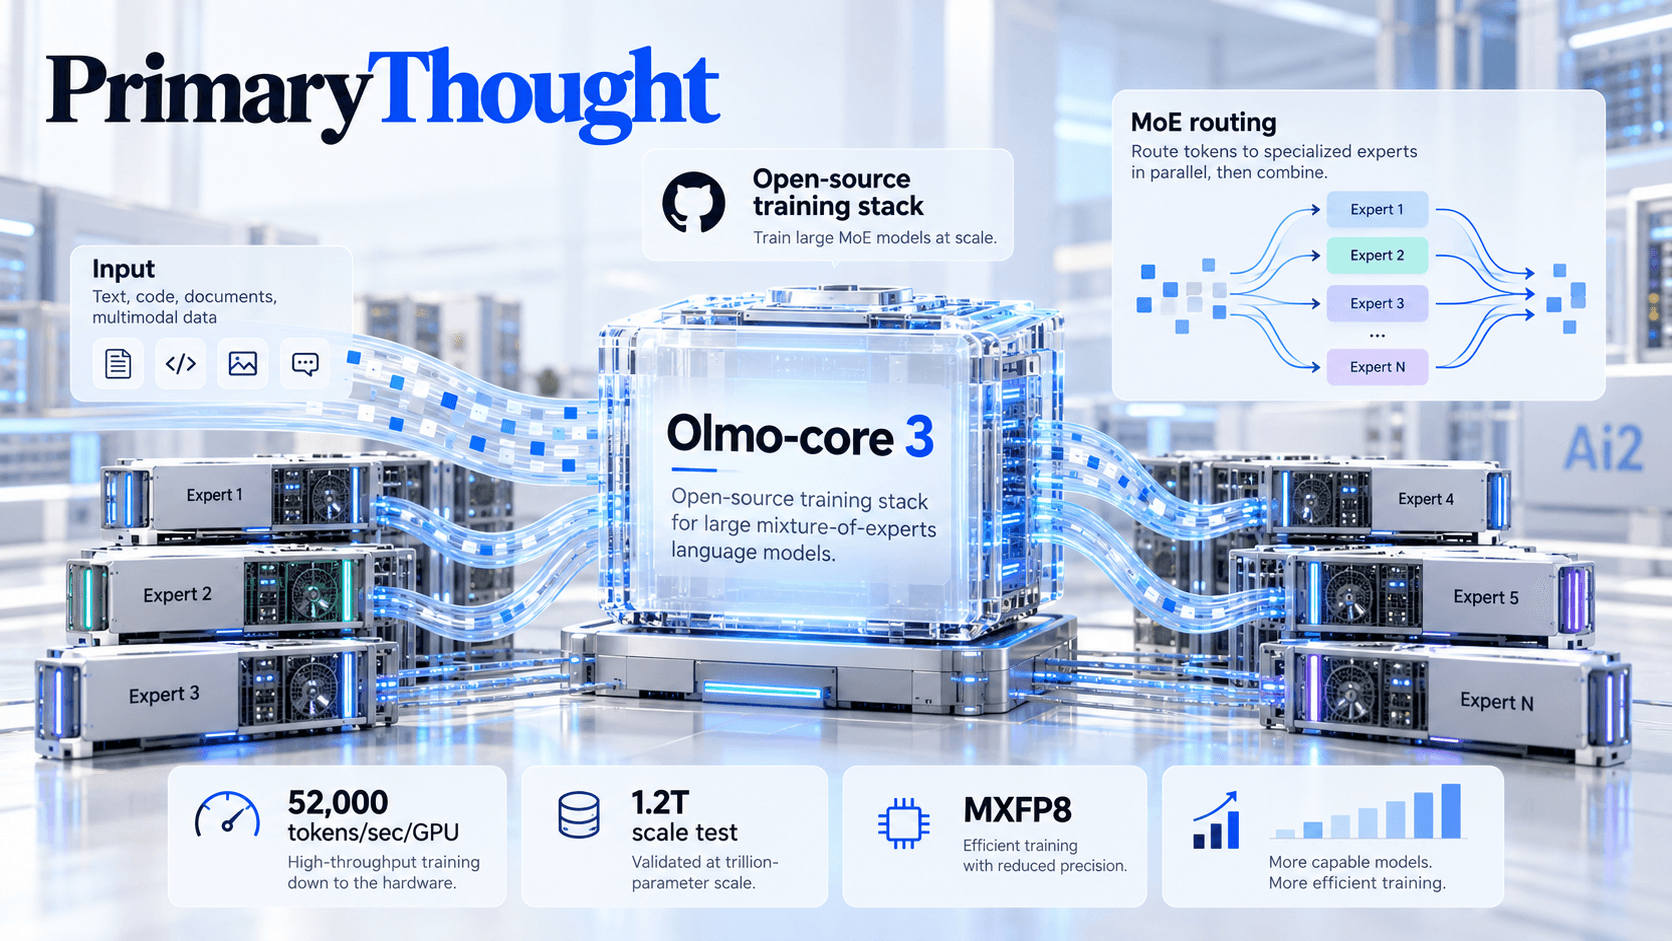
The Allen Institute for AI (AI2) has released Olmo-core 3, an open-source training stack for large mixture-of-experts (MoE) language models, along with a technical report detailing what worked and what did not. MoE training has become increasingly important for making large AI models more efficient, but many of the engineering techniques behind it have remained inside a small number of well-funded labs.
According to Ai2's announcement, a 47-billion-parameter MoE processed 52,000 tokens per second per GPU using Olmo-core 3. Those figures come from Ai2's own tests on NVIDIA B300 hardware, and the sources reviewed here do not report any outside group reproducing the result.
What Ai2 released
Olmo-core 3 is a code release, published on GitHub, with a technical report and an interactive demo. It is a training framework rather than a model: the point is to let researchers train their own MoE models and to adapt the system to different hardware and parallelism strategies. Ai2 says it has demonstrated configurations up to 1.2 trillion parameters across 512 GPUs, which is a scale test of the software rather than a released model of that size.
In an MoE model, each token is routed to a small subset of "expert" sub-networks, so total parameter count can grow without a matching rise in compute per token. That flexibility comes with systems problems: experts must be spread across many GPUs, tokens must be shuffled to the right devices and back, and routing decisions must stay balanced so no single GPU becomes a bottleneck. Olmo-core 3 is built around those problems.
The main techniques
Ai2 highlights several components in the stack. Expert parallelism spreads different experts across GPUs, reducing how much memory each card needs to hold. Pipeline parallelism divides the model's layers across groups of GPUs. A distributed optimizer spreads optimizer state across the hardware instead of storing a full copy on every device. Olmo-core 3 also keeps routing metadata on the GPU, which avoids data transfers that could slow computation, and supports MXFP8, a low-precision number format designed to reduce memory and computing demands.
The MXFP8 results are more specific. AI2 reports that enabling MXFP8 on four B300 GPUs increased training throughput by about 21 percent compared with BF16, while peak active memory fell from 103 GiB to 95 GiB. Using lower-precision formats to improve efficiency is not new, but getting both higher speed and lower memory use is valuable because available memory often limits how large a model or training batch can be.
The throughput claim in context
SiliconANGLE reports that the 52,000 tokens-per-second result compares with 19,400 for an earlier implementation, making it roughly 2.7 times faster, and identifies NVIDIA's Megatron-core as the comparison point. Other coverage of the release refers more generally to a previous implementation, so readers should check the technical report before citing the 2.7× figure as a direct Megatron-core comparison. The size of the speedup also depends on how the earlier system was configured: a poorly tuned baseline can make the gain look larger, while a well-optimized one makes the result more meaningful.
SiliconANGLE also reports that Ai2 increased the number of available experts from 8 to 128 while still selecting 4 experts for each token. This is the more interesting experiment for practitioners. Adding more experts increases the model's total parameter count sharply while keeping the compute used per token roughly the same. A training system that maintains throughput as the number of experts grows makes sparse scaling cheaper to test. The exact performance drop is not confirmed by the pages reviewed for this article, so it is not stated here.
Honest reporting of what failed
One of the more useful aspects of the release is that Ai2's report documents problems, according to its announcement. It describes "token gerrymandering," a case where routing metrics improve while actual load balancing gets worse. In other words, a number that looks like progress can hide uneven GPU utilization. Teams that tune MoE routers by watching a single balance metric could be misled in the same way.
The report also records cases where overlapping GPU streams, a common optimization that runs communication and computation at the same time, reduced throughput rather than improving it. That is a reminder that optimizations which help in one configuration can hurt in another, and that profiling beats assumptions.
Why it matters for ML engineering
For most organizations, training a trillion-parameter MoE is out of reach financially. The value of an open stack lies elsewhere. Smaller teams can read working implementations of expert parallelism and routing, reproduce scaled-down experiments, and port ideas to their own hardware. Academic groups gain a reference against which to compare new routing or parallelism methods, which is difficult when the leading systems are proprietary.
There is also a transparency benefit. Open training code lets outsiders check claims about efficiency and see which design decisions drive them. Including negative results in the report is consistent with that openness. Whether the stack becomes a community standard will depend on documentation quality, hardware portability, and how well it works outside Ai2's own cluster, none of which can be judged from launch coverage.
Caveats and open questions
There are several caveats. The headline figures come from Ai2 and were measured on NVIDIA B300 GPUs, a newer and less widely available class of hardware than many labs use. The sources reviewed do not report results on older accelerators or non-NVIDIA chips. The 1.2-trillion-parameter run shows that the software can scale to very large models, but it does not indicate how good a model trained at that size would be. The reported throughput gain also says nothing about final model quality, which still depends on factors such as training data, hyperparameters, and routing behavior.
Readers should also separate the framework's efficiency from the economics of training. Higher tokens per second reduces cost per token, but total cost still scales with the number of tokens and the cluster size.
The Next Test for Olmo-core 3
The next useful evidence will come from teams outside Ai2. If independent researchers can reproduce the 47-billion-parameter benchmark, run Olmo-core 3 on other hardware, and use it successfully in new open models, that would show whether the reported efficiency gains hold up more broadly. Further work on the routing and overlap issues described in the report will also matter, since similar problems are likely to appear in other large MoE training runs. For now, Olmo-core 3 is best seen as a well-documented, open reference implementation with promising results from Ai2 that still need wider testing.
Frequently Asked Questions
What is Olmo-core 3?
An open-source framework from Ai2 for training large mixture-of-experts language models, released on GitHub with a technical report and interactive demo.
What throughput does Ai2 report?
Ai2 says a 47-billion-parameter MoE processed 52,000 tokens per second per GPU on NVIDIA B300 hardware. SiliconANGLE reports a 2.7x gain over an earlier 19,400 tokens per second implementation.
What does MXFP8 change?
Ai2 reports about 21% higher training throughput than BF16 on four B300 GPUs, with peak active memory falling from 103 GiB to 95 GiB.
Were any problems reported?
Yes. The report describes token gerrymandering, where routing metrics improve while load balancing worsens, and cases where overlapping GPU streams reduced throughput.
Related articles
 Machine Learning
Kronecker Product Attention Claims 10x KV Cache Savings
A new arXiv preprint factorises the KV cache with Kronecker products, claiming up to 10x compression on small models. The evidence is early.
 Machine Learning
MLPerf Training Adds First LLM Post-Training Benchmark
MLPerf Training v6.1 will time how fast systems train Qwen 3.5 397B with reinforcement learning to fix real software bugs.
 Machine Learning
DeepSeek Releases Six Open-Source Tools for Huawei Ascend
DeepSeek released six open-source components, including TileLang and DeepGEMM, to make Huawei Ascend chips easier to use for training and inference.